The post ATC Welcomes Ryan Kelsey as Director of Client Growth! appeared first on Advanced Technology Consulting (ATC).
]]>
ATC is excited to announce the addition of Ryan Kelsey as Director of Client Growth, marking an exciting new chapter in the company’s continued growth and commitment to delivering exceptional client experiences.
With 15 years of experience in the technology industry, Ryan brings a unique perspective shaped by his extensive background in sales, business development, and technology solutions. In his new role, Ryan will lead ATC’s client growth efforts, working alongside the team to strengthen existing relationships, expand ATC’s reach, and introduce more organizations to the value of independent, provider-neutral technology consulting.
Bringing a New Perspective to Client Growth
Ryan began his career at Cincinnati Bell and CBTS, where he developed a strong understanding of how large telecommunications providers and technology integrators operate, from solution development and pricing to delivery. He later joined CenterGrid, a private cloud and managed services provider, where he held responsibilities across sales, business development, and marketing while helping enterprise organizations navigate cloud infrastructure and emerging AI workloads.
Throughout his career, Ryan has gained firsthand insight into the complexities organizations face when evaluating technology providers, negotiating contracts, and making critical IT investments. Now, he is bringing that experience to the other side of the table.
“After spending my career on the provider side, I’m excited to use that experience to advocate for clients,” Ryan shared. “I know what a good provider looks like, what questions IT teams should be asking, and where challenges can arise. At ATC, I have the opportunity to put that knowledge to work helping organizations make the right decisions for their business.”
Ryan’s approach aligns closely with ATC’s mission to deliver the exact right solution through expertise, process, and partnerships. By understanding business challenges first and providing objective guidance, ATC helps organizations navigate an increasingly complex technology landscape with confidence.
Strengthening ATC’s Client Growth Team
As Director of Client Growth, Ryan will provide leadership and strategic direction to ATC’s growing client-facing team, including the Principal Consultants.
Together, the team brings complementary industry experience, strong client relationships, and a shared commitment to helping organizations achieve meaningful business outcomes through technology.
With Ryan’s leadership, ATC will continue building on its established presence while creating new opportunities to serve organizations across the region. The team’s focus will be on deepening client partnerships, identifying opportunities for innovation, and ensuring organizations have access to the expertise, resources, and provider ecosystem needed to make informed technology decisions more quickly, with confidence.
“Ryan has worked alongside ATC for over 12 years across different roles and companies. We know how he operates, how he treats people, and how he shows up for clients. He has ATC’s culture in his DNA,” said Nick Enger, President & CTO of ATC. “As Director of Client Growth, Ryan will help clients navigate the overwhelming technology landscape and help them make confident decisions that support their growth. He knows the provider side inside and out, and we’re excited to put that experience to work for our clients.”
A Shared Commitment to Putting Clients First
For Ryan, joining ATC was about more than a new leadership opportunity. It was about finding an organization whose culture and approach to client relationships aligned with his own values.
“What stood out to me was the culture,” Ryan explained. “This is a team that genuinely cares about the people involved, the outcomes, and the process it takes to get there. Everyone holds themselves to a high standard, and that translates directly into the experience clients receive.”
Having worked alongside ATC for years, Ryan was already familiar with the team and the value of its independent approach to technology consulting. After spending his career on the provider side, he saw an opportunity to take his experience in a new direction, working on behalf of clients rather than representing a single technology provider. For Ryan, joining ATC means becoming part of a team and an approach he’s believed in for years.
“A lot of business leaders still don’t realize that an independent technology advisor is an option,” Ryan said. “My goal is to introduce more organizations to that approach, strengthen the relationships we’ve already built, and make sure ATC is the first call when a business has an important technology decision to make.”
Getting to Know Ryan Beyond the Office
Outside of work, Ryan is a dedicated husband, father of four, and active member of the local community. Much of his free time is spent coaching his children’s sports teams or cheering them on from the sidelines.
An early riser, Ryan enjoys starting his mornings with reading, writing, and personal development before the busy day begins. He also enjoys staying active, attending live music events, and exploring new restaurants around Cincinnati with his wife, Stephanie.
Looking Ahead
Ryan’s addition represents another important step in ATC’s continued investment in its team, its clients, and the communities it serves. With his industry expertise, relationship-driven approach, and passion for helping organizations succeed, Ryan will play a key role in expanding ATC’s impact and supporting its next phase of growth.
Please join us in welcoming Ryan Kelsey to the ATC team!
The post ATC Welcomes Ryan Kelsey as Director of Client Growth! appeared first on Advanced Technology Consulting (ATC).
]]>The post ATC Joins Ohio Tech Leaders at the OhioX CEO Retreat appeared first on Advanced Technology Consulting (ATC).
]]>Nick participated in “When the Market Moves: Leading Through AI, Disruption, and Change,” a panel exploring how leaders make decisions as AI changes customer expectations, team structures, and the pace of business. The conversation reflected a question many organizations face today: where should they adapt, experiment, and invest while keeping their business goals in focus?
“The energy and connections in the room at this year’s OhioX CEO Retreat were incredible to see—these are the folks shaping Ohio’s future, and I was proud to represent ATC in that conversation. I’d like to give a huge thank you to Chris Berry for bringing leaders from across Ohio together and building relationships that lift up the whole Ohio community.”
– Nick Enger, President & CTO, ATC
Thank you to OhioX for creating space for leaders across the state to share perspectives and build connections. We were glad to be part of this year’s retreat.
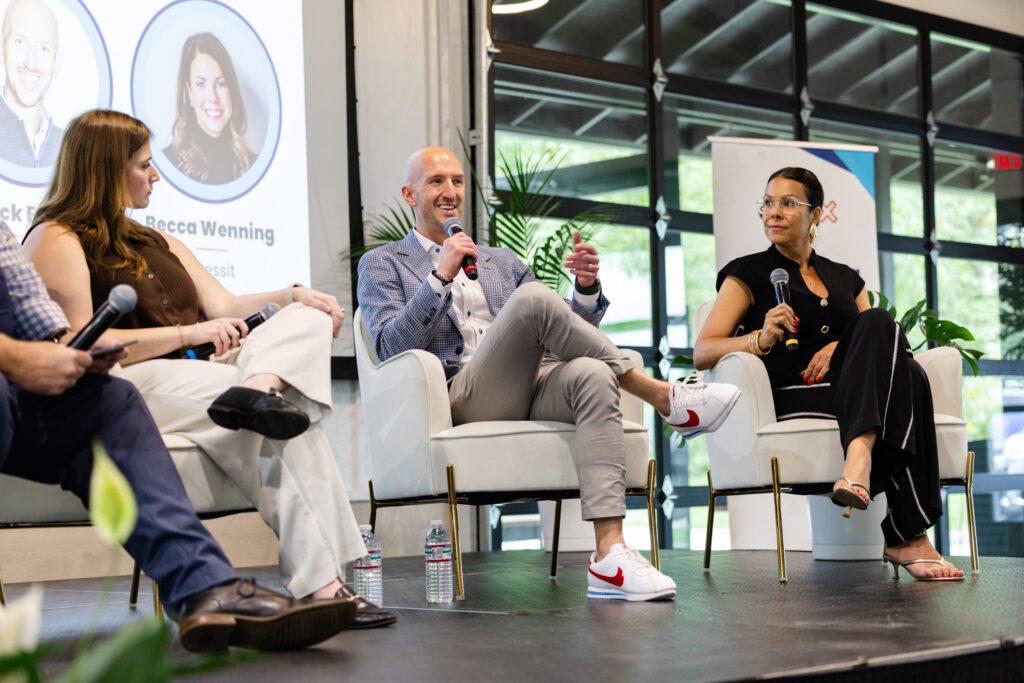
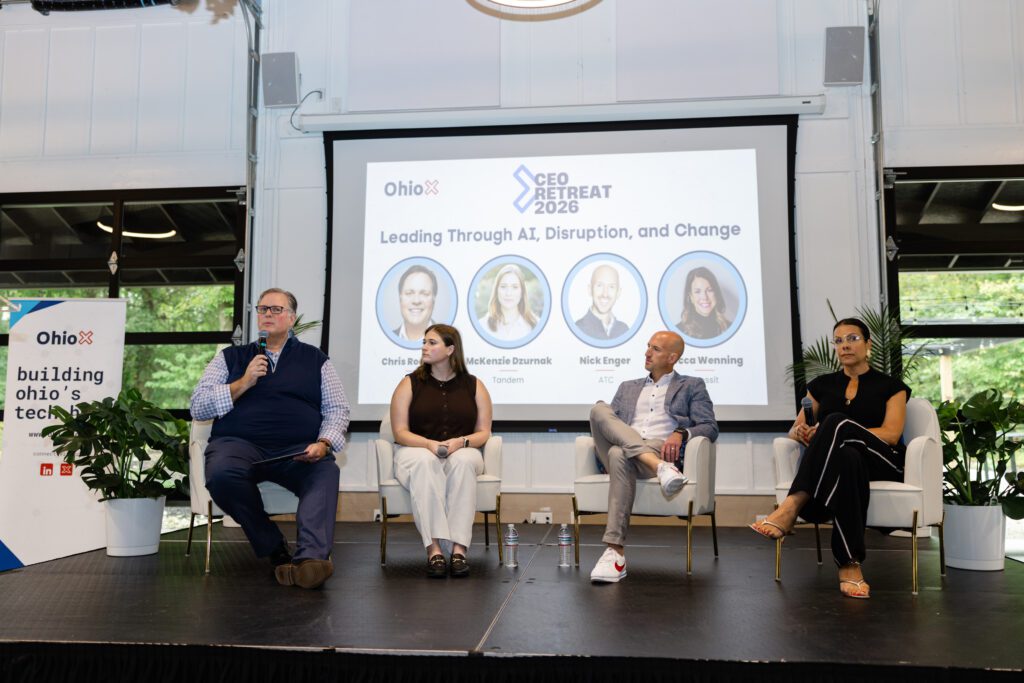
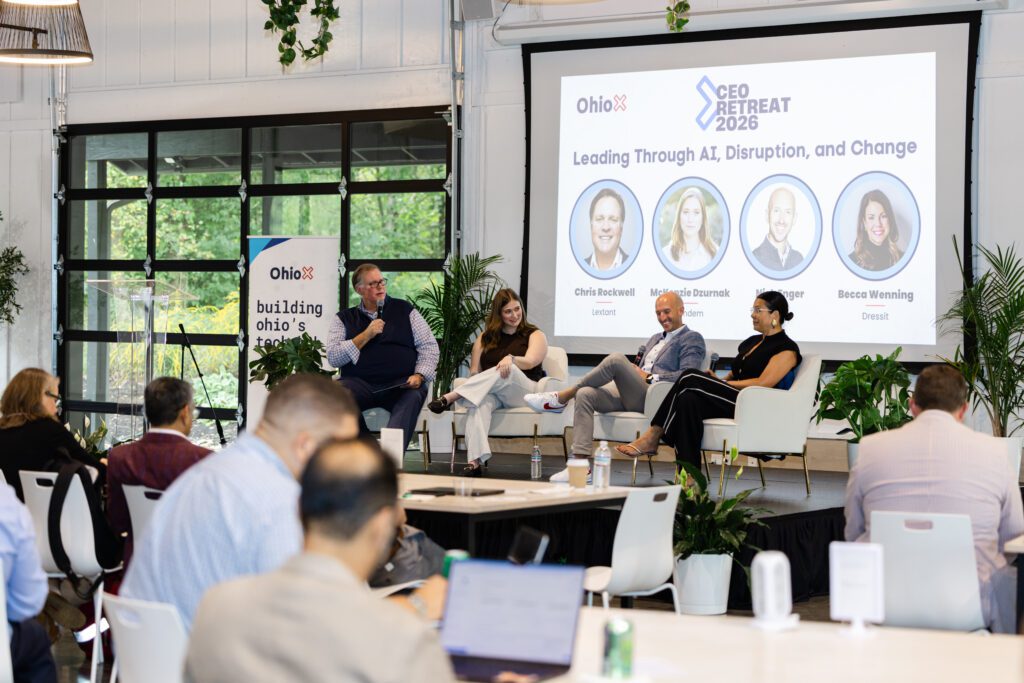
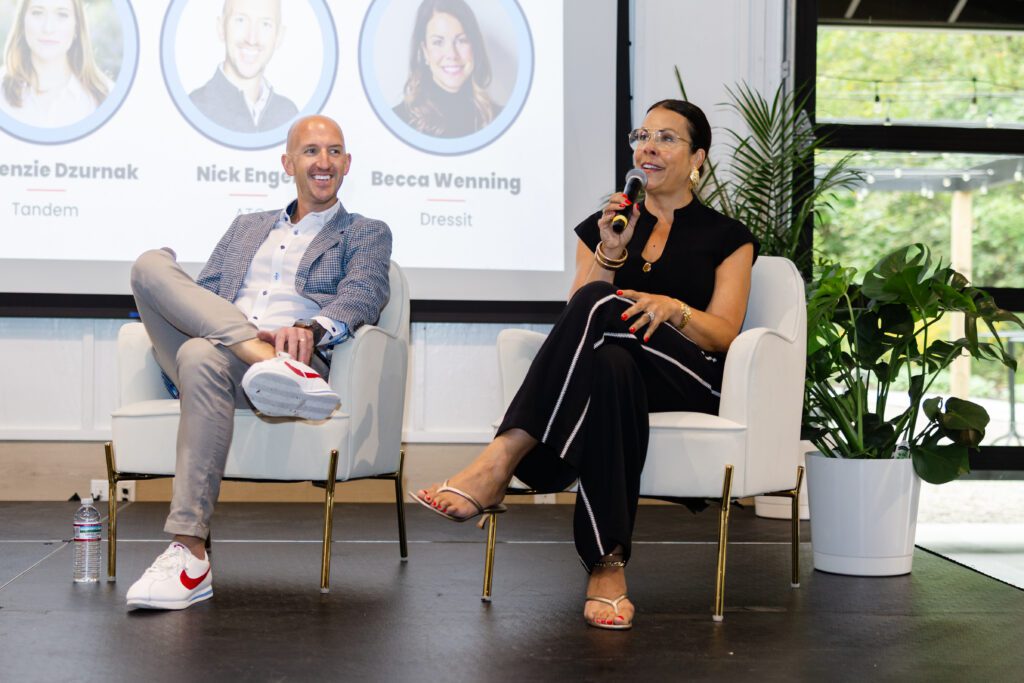
ATC President and CTO Nick Enger speaks during the “Leading Through AI, Disruption, and Change” panel at the 2026 OhioX CEO Retreat.
The post ATC Joins Ohio Tech Leaders at the OhioX CEO Retreat appeared first on Advanced Technology Consulting (ATC).
]]>The post ATC Welcomes Trevor Cobain to the Principal Consultant Team! appeared first on Advanced Technology Consulting (ATC).
]]>
ATC is excited to welcome Trevor Cobain to the team as our new Principal Consultant.
Trevor brings a strong background in technology and a career dedicated to helping clients achieve their goals. His ability to understand complex challenges, build trusted relationships, and connect organizations with the right strategy, people, and technology will make him an asset to ATC and the clients we serve.
As a Principal Consultant, Trevor will work closely with organizations to understand their business priorities, identify opportunities, and help navigate increasingly complex technology decisions.
“I’ve built my career around helping clients succeed. I’m passionate about understanding what they’re trying to accomplish, earning their trust, and helping them navigate challenges with the right strategy, people, and technology,” Trevor shared. “That’s what makes ATC such a great fit for me. Its client-first, consultative approach closely matches how I’ve always believed strong business relationships should work.”
Outside of work, Trevor is an avid record collector and music-history enthusiast. His collection and interest in music have given him an appreciation for the stories, people, and moments behind some of his favorite records.
He also has a longtime fascination with automotive history and vintage cars—another interest rooted in understanding how things have evolved over time and appreciating the details that make them unique.
We’re thrilled to have Trevor join ATC and look forward to the experience, perspective, and client-focused leadership he will bring to our team.
Welcome to ATC, Trevor!
The post ATC Welcomes Trevor Cobain to the Principal Consultant Team! appeared first on Advanced Technology Consulting (ATC).
]]>The post From Firefighting to Foresight, How One CTO Rebuilt Their Technology Roadmap appeared first on Advanced Technology Consulting (ATC).
]]>
For a lot of CTOs, the roadmap looks solid on paper.
It outlines initiatives. It aligns to business priorities. It reflects input from across the organization. At the start of the year, it feels structured and achievable.
By the second quarter, it starts to break.
New requests come in. Priorities shift. Incidents consume time. Dependencies surface that were not fully understood. Projects slip. The roadmap becomes less of a plan and more of a loose reference point.
This is a familiar pattern, and it is exactly where IT roadmap for CTOs tends to fall apart.
The starting point, constant firefighting
In this case, the CTO was not lacking vision.
The organization had clear goals. There was alignment with the business. The team was capable. The issue was not strategy. It was execution under pressure.
The environment looked like this:
- multiple high-priority initiatives running in parallel
- limited visibility into cross-team dependencies
- reactive work constantly interrupting planned work
- funding tied to projects instead of outcomes
- teams operating with different assumptions about priority
None of these issues were unusual. That was part of the problem. They were accepted as normal.
But the cumulative effect was significant. The roadmap was constantly being reshaped by short-term demands. Long-term initiatives slowed down. Teams became more reactive. Leadership spent more time reprioritizing than executing.
This is where IT roadmap for CTOs often becomes an exercise in managing disruption instead of driving direction.
The turning point, redefining what the roadmap actually is
The shift did not start with new tools or new frameworks.
It started with a different definition of the roadmap.
Instead of treating the roadmap as a list of projects, it was reframed as a system for making decisions. That sounds subtle, but it changed how everything was approached.
Projects were no longer the unit of planning. Outcomes were.
This forced a more disciplined conversation. If an initiative did not clearly connect to a defined outcome, it was deprioritized. If multiple initiatives were trying to achieve the same outcome, they were consolidated.
That clarity reduced noise quickly.
It also exposed where effort was being spread too thin.
Dependency mapping made the invisible visible
One of the biggest constraints was not obvious at first.
Projects were slipping, but not because teams were underperforming. They were waiting on each other.
Dependencies existed across infrastructure, applications, data, and external vendors. They were understood at a local level but not consistently mapped across the organization.
This is where dependency mapping became critical.
By making dependencies explicit, the team was able to see where sequencing mattered. Some initiatives that looked independent were actually tightly coupled. Others could move forward in parallel once the right constraints were removed.
This changed how prioritization worked.
Instead of asking “What is most important,” the conversation shifted to “What needs to happen first for everything else to move.”
That is a very different lens for an IT roadmap for CTOs. It aligns effort with flow, not just priority.
Prioritization became about trade-offs, not alignment
Most prioritization processes aim for alignment.
Everyone agrees on what matters. Everything feels important. The result is a long list of initiatives that all have some level of justification.
That was part of the problem.
The shift here was toward explicit trade-offs.
Instead of asking teams to rank priorities, the CTO asked a harder question: what are we not going to do right now?
That forced clarity.
Initiatives that did not make the cut were not left in a “next up” category. They were paused with intention. That created space for the remaining work to move forward with fewer interruptions.
This is one of the more difficult aspects of IT roadmap for CTOs. It requires saying no in a way that is visible and sustained.
Funding models were reinforcing the wrong behavior
Another issue sat underneath the roadmap.
Funding was tied to projects.
Each initiative had its own budget, its own justification, and its own expectations. That structure made it difficult to shift resources when priorities changed. It also encouraged teams to protect their projects rather than adapt to new information.
The adjustment was not immediate, but it was important.
Funding started to move toward broader capability areas instead of individual projects. That created more flexibility. Resources could be redirected without restarting approval processes. Teams could respond to change without breaking the system.
This is often overlooked in IT roadmap for CTOs. The funding model either supports adaptability or works against it.
The result was not a perfect roadmap, but a more stable system
The outcome was not a roadmap that never changed.
That is not realistic.
What changed was how the roadmap responded to change.
New requests still came in. Priorities still shifted. Incidents still happened. But the system was better equipped to absorb those changes without losing direction.
Dependencies were clearer. Trade-offs were more explicit. Teams understood how their work connected to outcomes. Leadership spent less time reacting and more time guiding.
The roadmap became more resilient.
What actually changed day to day
From the outside, the shift looked strategic.
From the inside, it showed up in small ways.
Fewer meetings spent rehashing priorities. More clarity in how decisions were made. Less context switching for teams. Better sequencing of work. More predictable progress on key initiatives.
This is where IT roadmap for CTOs becomes tangible. It is not just about the document. It is about how the organization operates around it.
The lesson most teams miss
The instinct when a roadmap breaks is to fix the roadmap.
Add more detail. Improve tracking. Introduce new tools. Refine the planning process.
Those things can help, but they do not address the underlying issue.
The problem is usually structural.
It sits in how priorities are defined, how dependencies are managed, how funding is allocated, and how decisions are made under pressure.
That is why rebuilding an IT roadmap for CTOs is rarely about the roadmap itself. It is about the system that supports it.
The better question for CTOs
Instead of asking whether the roadmap is accurate, a better question is:
Does the system behind the roadmap help us make better decisions when things change?
That question gets closer to the real challenge.
Because things will change.
The goal is not to prevent that. The goal is to respond without losing direction.
That is the difference between firefighting and foresight.
The post From Firefighting to Foresight, How One CTO Rebuilt Their Technology Roadmap appeared first on Advanced Technology Consulting (ATC).
]]>The post Lumen Changed Direction. Is Your Communications Roadmap Still Valid? appeared first on Advanced Technology Consulting (ATC).
]]>
Every few years, the enterprise technology market delivers the same uncomfortable reminder: vendors make strategic decisions based on their businesses, while customers must make decisions based on theirs.
Lumen Technologies’ decision to pull back from voice products is the latest example. The company is shifting attention toward networking, AI infrastructure, network-as-a-service offerings, and its recently acquired Alkira portfolio. It has also reduced roles within its commercial and partner organizations as part of that realignment.
From Lumen’s perspective, that may be a logical business move. Companies routinely concentrate investment in the markets where they see the strongest growth and differentiation.
But an enterprise customer has a different question to answer.
What does the vendor’s new direction mean for our technology environment?
That is where technology roadmap planning becomes more important than reacting to a single announcement.
This Is Not Really a Story About Lumen
It would be easy to interpret the news as a warning specifically for Lumen voice customers. Existing customers may understandably have questions about renewals, support, future product development, and what happens when their current agreements expire.
Those are valid questions, but the larger lesson applies far beyond one carrier.
Technology vendors change priorities all the time. Leadership teams turn over. Product lines are consolidated. Acquisitions reshape portfolios. Support models change. Platforms that were once central to a vendor’s strategy can become secondary surprisingly quickly.
None of that automatically means a customer should leave.
It does mean customers should stop assuming that yesterday’s vendor commitment guarantees tomorrow’s investment.
Good technology roadmap planning accounts for that possibility before a change becomes urgent.
A Vendor Roadmap Is Not Your Technology Roadmap
Enterprise IT teams often spend years building around major technology providers. Over time, products become deeply embedded in operations, contracts, workflows, integrations, and user habits.
That history can create a subtle but significant risk. The organization’s roadmap begins to follow the vendor’s roadmap by default.
When a provider launches a new platform, the organization considers adopting it. When the provider bundles services, the organization expands its commitment. When the provider changes direction, the customer suddenly faces pressure to change direction too.
That is backwards.
A vendor roadmap explains where the vendor wants to go. Your technology roadmap should explain where your business needs to go.
The two may align, but alignment should be tested, not assumed.
Effective technology roadmap planning starts with business requirements, operational priorities, risk tolerance, user needs, and financial realities. Products and providers come later.
That distinction becomes especially important when a long-standing provider begins deprioritizing a service that remains important to your organization.
Do Not Confuse Stability With Permanence
Large, established vendors are often selected partly because they appear stable. That instinct makes sense. Enterprise IT leaders want reliable partners, predictable service, and confidence that critical platforms will be supported.
But stability and permanence are not the same thing.
A provider can remain financially and operationally significant while still exiting a product category. A platform can continue functioning while receiving less commercial attention. A contract can remain valid while the surrounding support, escalation, and innovation ecosystem gradually changes.
Nothing has to fail overnight for risk to increase.
That is why technology roadmap planning should look beyond whether a service is currently operational. IT leaders should also evaluate whether the provider is still investing in the people, capabilities, partnerships, and product development needed to support it over time.
The right question is not simply, “Does it still work?”
The better question is, “Is this still where the vendor is placing its energy?”
What Should Current Customers Be Asking?
The first response to a strategic vendor shift should not be panic. It should be structured curiosity.
For organizations currently using Lumen voice services, the immediate priority is gaining clarity. What products are affected? How will renewals be handled? What support resources will remain available? Will service levels, escalation paths, or account coverage change? Which capabilities will continue to receive investment?
The answers may vary by product, contract, and customer environment.
Organizations should also examine their own reasons for staying. Is the current platform still the best fit, or has it simply become familiar? Are there integrations or dependencies that would make migration difficult? How much time would a responsible transition require? When does the current contract create a natural decision point?
These questions are not an argument for leaving immediately. They are the foundation of responsible technology roadmap planning.
A well-run review will provide clarity on the best pathway forward now and into the future. The value comes from making that decision deliberately rather than allowing inertia to make it by default.
Architecture Matters More Than Product Loyalty
Vendor changes also expose a broader architectural issue.
Organizations that build highly portable, well-documented, and adaptable environments generally have more options when providers change course. Organizations with tightly coupled systems, unclear dependencies, and limited internal documentation often discover that changing one service affects far more of the environment than expected.
This is why architecture matters more than allegiance to any particular product.
A flexible communications environment should make it possible to evaluate new platforms without redesigning the entire enterprise. Contracts should preserve reasonable transition options. Integrations should be documented. Numbers, routing requirements, compliance considerations, user groups, interconnectivity, contact center dependencies, and business continuity needs should be understood before a migration becomes necessary.
Strong technology roadmap planning does not eliminate vendor risk. It reduces the organization’s dependence on any one vendor decision.
The objective is not to avoid long-term partnerships. Strategic providers can deliver enormous value.
The objective is to ensure that a provider’s internal business decision does not automatically become your emergency.
Waiting for Certainty Can Become Its Own Risk
One of the hardest parts of responding to a vendor shift is that details often emerge gradually.
Customers may hear an initial announcement, followed by policy clarifications, revised compensation rules, product-specific guidance, and eventually more formal transition plans. During that period, it may be tempting to wait until every question has been answered.
Waiting may be appropriate for an immediate purchasing decision. It should not prevent internal planning.
Organizations can begin documenting their current environment, reviewing contracts, identifying dependencies, evaluating realistic alternatives, and estimating migration timelines without making a premature commitment.
That work creates options.
If the provider clarifies its strategy and the existing service remains a strong fit, the organization can stay with greater confidence. If the outlook becomes less favorable, the team will not be starting from zero.
That is the practical value of technology roadmap planning. It replaces speculation with preparation.
The Larger Lesson for IT Leaders
Lumen’s voice pivot should not be treated as a crisis, nor should it be dismissed as routine industry news.
It is a reminder that vendor priorities are temporary by nature.
Today’s strategic platform can become tomorrow’s legacy product. A provider that once positioned itself as a one-stop shop may decide to specialize. A service that remains valuable to customers may no longer fit the vendor’s growth strategy.
That does not make the vendor wrong. It simply means the customer must maintain an independent point of view.
Every major provider announcement should trigger the same question:
Does our current direction still reflect our business priorities, or are we following someone else’s?
Organizations with disciplined technology roadmap planning do not need to react emotionally when a vendor changes course. They already understand their environment, their alternatives, their decision points, and the outcomes they are trying to protect.
Lumen is the headline today.
The more enduring lesson is that no vendor should own your strategy.
The post Lumen Changed Direction. Is Your Communications Roadmap Still Valid? appeared first on Advanced Technology Consulting (ATC).
]]>The post ATC’s Delta Team Achieves 100% PMP Certification appeared first on Advanced Technology Consulting (ATC).
]]>
At ATC, delivering successful technology projects starts with investing in our people. We’re proud to announce that every member of our consulting team is now Project Management Professional (PMP)® certified through the Project Management Institute (PMI).
The PMP certification is widely recognized as the global standard for project management professionals. Earning the credential is a rigorous process that requires a combination of real-world project leadership experience, formal project management education, and passing a comprehensive exam covering the full project lifecycle.
The certification validates a professional’s ability to:
- Lead projects from initiation through completion
- Manage scope, schedules, budgets, and resources
- Identify and mitigate project risks
- Communicate effectively with stakeholders and executive leadership
- Apply predictive, agile, and hybrid project management methodologies based on each project’s unique needs
Because maintaining the certification requires ongoing professional development and continuing education, PMP-certified professionals stay current on evolving best practices and emerging trends in project management.
For our clients, this milestone reinforces what they can expect from every engagement with ATC:
- Proven project management expertise
- Consistent, disciplined delivery methodologies
- Strong communication and stakeholder alignment
- A commitment to delivering projects on time, on budget, and with measurable results
While certifications are important, they’re only part of the story. Our consultants combine technical expertise with real-world experience to help organizations navigate complex IT initiatives with confidence.
Achieving 100% PMP certification across our consulting team reflects our ongoing investment in excellence—and our commitment to delivering exceptional outcomes for every client, every project.
Congratulations to our entire Delta Consulting Team on this outstanding accomplishment!
The post ATC’s Delta Team Achieves 100% PMP Certification appeared first on Advanced Technology Consulting (ATC).
]]>The post Hybrid Isn’t a Compromise, Designing for Flexibility, Not Purity appeared first on Advanced Technology Consulting (ATC).
]]>
For a while, hybrid carried the wrong reputation.
It sounded like hesitation. Like a half-step. Like an organization that could not fully commit to cloud. In some cases, that was true. In many others, it was a misread. What looked like indecision was actually realism.
That is why hybrid cloud architecture strategy matters more now than it did when “cloud-first” became the default narrative. The conversation has shifted. The question is no longer whether everything should move. The question is what should move, what should not, and how the environment behaves once it is distributed.
The providers themselves have been signaling this shift. Google’s hybrid and multicloud guidance starts from business constraints, data location, and workload requirements, not from a single destination model. Hybrid is a deliberate architectural pattern, not a transitional phase.
The problem with purity-based architecture
A lot of cloud strategy conversations still get framed around purity.
All-in cloud. All-in on a single provider. Full standardization. Clean diagrams. It sounds efficient. It looks simple. It rarely survives contact with enterprise reality.
Most environments are not greenfield. They are shaped by:
- legacy systems that still matter
- applications that are tightly coupled
- data that does not move easily
- regulatory constraints
- latency-sensitive workloads
- physical locations that matter
- operational models that cannot be rewritten overnight
This is where hybrid cloud architecture strategy stops being optional and starts becoming necessary.
Trying to force purity into a mixed environment usually creates more complexity, not less. Workloads get moved without being redesigned. Latency gets worse. Costs drift. Governance becomes harder. The environment looks cleaner in a diagram and messier in practice.
That is one of the more expensive architecture mistakes CTOs still see, designing for ideological consistency instead of operational reality.
When hybrid is actually the better choice
One of the better questions technical leaders can ask is simple, when is hybrid better than cloud only?
The answer usually shows up in patterns, not theory.
Hybrid tends to win when:
- Data gravity is real
Large datasets, tightly coupled systems, or data residency constraints make relocation expensive, slow, or risky. Moving the compute closer to the data is often more practical than moving the data itself. - Latency matters more than flexibility
Real-time systems, manufacturing environments, financial systems, and edge-driven applications cannot always tolerate round-trip delays to a centralized cloud region. - Compliance requirements shape architecture
Certain industries require tighter control over data location, access, and processing. A hybrid model allows separation of sensitive workloads without abandoning cloud advantages elsewhere. - Edge environments are part of the system
Retail, healthcare, logistics, and distributed operations often require local processing, local resilience, and intermittent connectivity handling that pure cloud models struggle to support cleanly. - Modernization is happening in phases
Not every system can or should be transformed at once. Hybrid allows sequencing without forcing unstable migrations.
None of these scenarios are edge cases. They are normal enterprise conditions. That is why hybrid cloud architecture strategy is less about compromise and more about alignment.
Data gravity is still one of the most underestimated forces
Data gravity tends to get mentioned early in architecture discussions and then quietly ignored when timelines tighten.
That is a mistake.
Large, complex datasets do not move easily. Even when they can, the cost, time, risk, and downstream dependencies often outweigh the theoretical benefits of relocation. Applications built around those datasets inherit that constraint whether teams acknowledge it or not.
This is where hybrid cloud architecture strategy becomes practical instead of philosophical. Instead of forcing data movement, strong teams design around it. They bring compute closer to the data, segment workloads intelligently, and avoid unnecessary replication patterns that create more problems than they solve.
Ignoring data gravity does not eliminate it. It just turns it into a performance problem later.
Hybrid architecture is really about control points
A lot of teams think about hybrid in terms of “some on-prem, some cloud.”
That framing is too shallow.
A better way to think about hybrid cloud architecture strategy is in terms of control points:
- where data lives
- where compute runs
- where decisions are made
- where latency is introduced
- where security boundaries sit
- where failure can occur
Once those are defined, the environment becomes easier to reason about. Hybrid stops being a mix of locations and starts becoming a system with intentional boundaries.
That is where architecture becomes more resilient. Not because everything is centralized, but because the dependencies are clearer and the failure domains are better understood.
Designing hybrid for resilience
Another common question is how to design hybrid for resilience.
The wrong approach is to treat hybrid as a backup plan. The better approach is to treat it as a distributed system from the start.
That means:
- designing for failure across boundaries, not just within a single environment
- ensuring network paths are intentional, not incidental
- planning for degraded states, not just full availability
- understanding how applications behave when one side of the architecture is unavailable
- avoiding tight coupling between cloud and on-prem components where it creates fragility
Resilience in hybrid environments is not automatic. It comes from understanding how the system behaves under stress, not just how it performs when everything is working.
This is also where network design becomes tightly coupled with cloud design. Poor pathing, weak redundancy, or unclear failover logic can undermine even well-placed workloads.
The hidden risk is operational complexity
One of the valid criticisms of hybrid is complexity. That criticism is not wrong.
Hybrid cloud architecture strategy introduces:
- multiple environments
- multiple control planes
- multiple cost models
- more governance requirements
- more operational coordination
The mistake is assuming cloud-only eliminates those problems. In many cases, it just hides them in different places.
Strong teams manage this by being explicit about ownership, standards, and operating models. They define:
- who owns each environment
- how changes are governed
- how costs are tracked
- how performance is measured
- how incidents are handled across boundaries
Without that discipline, hybrid becomes messy. With it, hybrid becomes flexible.
Flexibility is the real goal
That is the part that often gets missed.
The goal is not to achieve a perfect architecture diagram. The goal is to give the business flexibility without sacrificing performance, resilience, or control.
Hybrid cloud architecture strategy supports that when it is done intentionally. It allows:
- different workloads to live in the environments that suit them best
- organizations to evolve without forced migrations
- better alignment between technical design and business constraints
- more realistic modernization timelines
That is why hybrid is not a compromise. It is often the more mature position.
The better question for CTOs
Instead of asking whether the organization is cloud-first enough, the better question is this:
Is the architecture flexible enough to support what the business needs next?
That question leads to better decisions about:
- workload placement
- data strategy
- edge computing
- compliance requirements
- resilience design
It also avoids one of the more common cloud strategy pitfalls, confusing commitment with effectiveness.
The strongest technical leaders are not trying to prove that everything belongs in one place. They are building environments that can adapt without breaking.
That is what hybrid cloud architecture strategy is really about.
The post Hybrid Isn’t a Compromise, Designing for Flexibility, Not Purity appeared first on Advanced Technology Consulting (ATC).
]]>The post ATC’s David Goodwin Named to Xavier University Board of Trustees appeared first on Advanced Technology Consulting (ATC).
]]>
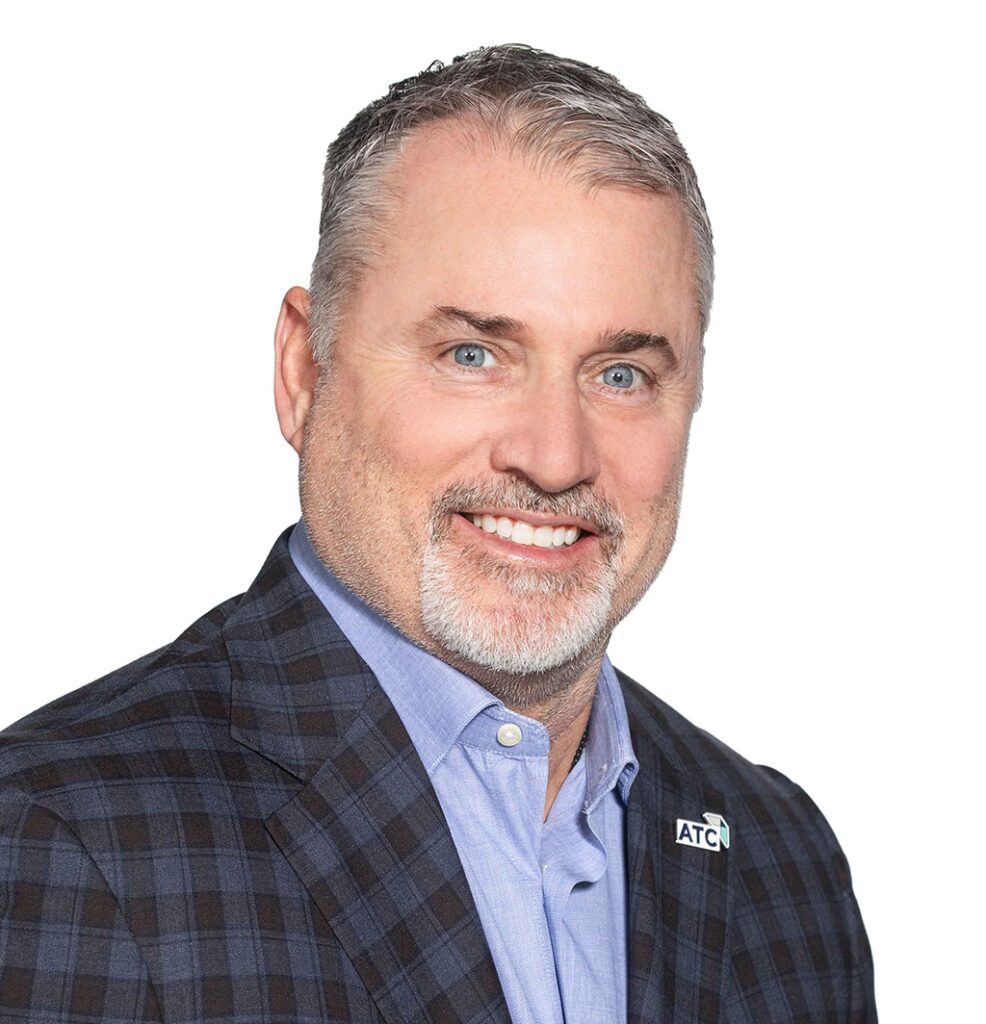
We’re proud to share some exciting news: David Goodwin, Co-Founder and CEO of ATC of Ohio, has been named to Xavier University’s Board of Trustees.
David is one of six new trustees announced this summer by Xavier President Colleen Hanycz, Ph.D., a cohort she described as bringing broad perspectives and a deep commitment to advancing the University’s mission at a pivotal time in its history.
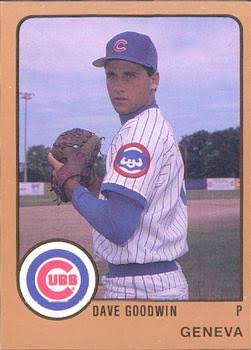
For David, the appointment marks the next chapter in a relationship with Xavier that began decades ago. A 1991 graduate, he arrived on campus as a standout baseball player and was drafted by the Chicago Cubs as a pitcher during his junior year. After completing his business management degree, he embarked on a career in the technology industry that ultimately led him to co-found ATC, where he has built a company recognized for its client-first approach, rapid growth, and exceptional service. David has previously served on Xavier’s President’s Advisory Council, deepening ties that now extend to the University’s highest governing body.
In his own words:
“I am honored and grateful to have been elected to the Board of Trustees of Xavier University.
Over the years, I have had the privilege of engaging with Xavier in many ways—as a student-athlete, donor, longtime MBB season ticket holder, PAC member, and proud supporter. Each experience has deepened my appreciation for the University’s mission and the transformative impact it has on students, our community, and future generations of leaders.
Serving as a Trustee is an opportunity to give back to an institution that played a significant role in shaping both my professional and personal foundation. I look forward to working alongside my fellow Trustees, University leadership, faculty, alumni, and supporters to advance Xavier’s mission and help ensure its continued strength and success for years to come.”
All of us here at ATC couldn’t be prouder. David’s appointment is a reflection of the same values he brings to our team every day — integrity, dedication, and a genuine commitment to the people and communities he serves. We look forward to seeing the impact he’ll make on Xavier’s board in the years ahead.
Congratulations, David! Let’s Go X!
Head to Xavier’s website to learn more: https://www.xavier.edu/now/2026/xavier-university-welcomes-6-new-trustees
The post ATC’s David Goodwin Named to Xavier University Board of Trustees appeared first on Advanced Technology Consulting (ATC).
]]>The post What Technical Leaders Get Wrong About “Cloud First” appeared first on Advanced Technology Consulting (ATC).
]]>
Cloud First sounded decisive when it first took hold. It signaled momentum, modernization, and a break from slow-moving infrastructure habits. In a lot of organizations, it was probably a necessary correction. The problem is that many teams stopped treating it like a strategic bias and started treating it like a rule.
That is where cloud first strategy pitfalls begin.
A cloud-first posture can be useful if it pushes the organization to stop defending outdated hosting decisions by default. It becomes dangerous when it turns into a substitute for architecture judgment. The strongest CTOs do not ask whether cloud is good. They ask which workloads benefit from which model, under which constraints, and at what operational cost.
The official guidance from the major cloud providers points in that direction more than people sometimes admit. AWS frames migration through the 7 Rs because not every workload should take the same path. Some are retained. Some are retired. Some are rehosted. Some are refactored. Google’s hybrid and multicloud strategy guidance likewise starts from business considerations, constraints, and workload realities rather than assuming one destination model is automatically right for everything.
That is the real issue with cloud first strategy pitfalls. The phrase can be useful. The dogma is not.
The mistake is not choosing cloud, it is choosing it too vaguely
A lot of weak cloud strategy starts with a slogan and works backward.
“We are going cloud first” sounds strong in a board deck. It says almost nothing about workload placement, latency sensitivity, data gravity, compliance exposure, network pathing, operational readiness, or the degree of modernization the environment can actually absorb. It is a directional statement, not a design decision.
That gap creates all kinds of trouble. Teams assume lift-and-shift is the same thing as modernization. Leadership assumes moving out of a data center automatically improves agility. Finance assumes cloud spend will naturally optimize over time. Operations inherits a more distributed environment with more dependencies and less tolerance for weak governance.
Those are classic cloud first strategy pitfalls because they all come from the same underlying issue, the business chose a destination before it made enough decisions about the road.
Workload placement is where the slogan usually breaks down
This is the part that tends to separate mature technical leadership from cloud enthusiasm.
Good cloud architecture is rarely about sending everything to the same place. It is about matching workloads to the environment that best fits their performance profile, resilience needs, data dependencies, security requirements, and economic realities. Google’s official hybrid and multicloud strategy guidance says this pretty directly, organizations should plan based on business drivers and constraints, not just target technologies. AWS’s migration guidance says the same thing through the 7 Rs model, the right treatment depends on the workload.
That is why workload placement deserves more attention than it usually gets in cloud-first conversations.
Some workloads benefit immediately from cloud elasticity and managed services. Some should be replatformed rather than simply moved. Some are too latency-sensitive, too entangled, too regulated, or too operationally awkward to move without creating new problems. Some should stay where they are for now because the business gets more value from simplification elsewhere first.
That is not anti-cloud thinking. It is architecture discipline.
Lift and shift is not a strategy, it is sometimes a holding pattern
This is one of the most common misunderstandings behind cloud first strategy pitfalls.
There are valid reasons to rehost. Rehosting can make sense when time is limited, modernization resources are constrained, or the workload needs to move before it can be changed more substantially. But that does not make rehosting a complete strategy. It makes it one possible move in a larger sequence.
The trouble starts when organizations treat rehosting as proof that the strategy is working. The server moved. The environment is now “in cloud.” The dashboard looks modernized. Meanwhile, the application is still chatty, still hard to govern, still expensive to operate, and still dependent on network patterns and operational assumptions that no longer fit.
That is one of the quieter cloud first strategy pitfalls. The business mistakes relocation for redesign.
Cost governance gets ignored until the bill becomes political
This is another pattern that shows up over and over.
A lot of cloud-first programs spend enormous energy on migration and surprisingly little on economic control. The assumption seems to be that cost discipline can be layered in later. In practice, later often means after bad habits are already embedded.
AWS’s cloud transformation guidance calls out value articulation and operating model challenges early in cloud adoption, not just technical concerns. That is important because cost governance is not really a finance issue alone. It is a behavior issue. It is tied to environment sprawl, ownership ambiguity, idle resources, duplicated services, weak tagging, poor lifecycle management, and unclear accountability for consumption.
This is where cloud first strategy pitfalls start to affect credibility at the leadership level. If cloud spend climbs faster than business value, the strategy gets framed as drift instead of modernization. Once that happens, every subsequent cloud decision becomes harder to defend, even the good ones.
Strong teams do not wait for the bill to create discipline. They build cost governance into provisioning, ownership, and operating review from the start.
Hybrid is not a compromise, it is often the grown-up answer
There is still a strange instinct in some leadership circles to treat hybrid like hesitation. That is usually a sign the conversation is too ideological.
Hybrid can absolutely be messy when it emerges by accident. It can also be the most rational design choice when it is intentional. Google’s planning guidance makes room for hybrid and multicloud because enterprise reality often includes data locality constraints, compliance requirements, edge use cases, legacy dependencies, and workload diversity that do not fit a single-cloud default.
This is why cloud first strategy pitfalls often come from confusing purity with maturity. The goal is not to achieve the most aesthetically consistent deployment model. The goal is to create an environment the business can operate, secure, and evolve.
Sometimes that means public cloud. Sometimes that means private infrastructure. Sometimes that means a hybrid model with a very clear reason for each boundary.
What technical leaders should ask instead
The better conversation is usually built around harder questions.
- What workload characteristics actually matter here?
- What dependencies make relocation expensive or risky?
- What does the network path look like after the move?
- What operating model changes are required to govern this well?
- Where will cost discipline come from?
- What should be modernized now, and what should simply be stabilized?
That is a more useful framework than asking whether the organization is “cloud first enough.”
The strongest teams are usually less interested in signaling commitment to cloud and more interested in avoiding avoidable design mistakes. They know cloud first strategy pitfalls tend to show up when strategic posture outruns engineering judgment.
The smarter version of cloud first
There is a version of cloud first that still makes sense.
It is not “put everything in cloud.”
It is “evaluate cloud early, but decide based on workload fit, economics, resilience, and operational readiness.”
That version is much less catchy. It is also much more likely to produce an environment the business can actually live with.
Cloud-first thinking becomes valuable when it breaks inertia. It becomes expensive when it replaces architecture. That is the line technical leaders need to hold.
The post What Technical Leaders Get Wrong About “Cloud First” appeared first on Advanced Technology Consulting (ATC).
]]>The post IT Stack Rationalization, A CTO’s Guide to Cutting Sprawl and Buying With Intent appeared first on Advanced Technology Consulting (ATC).
]]>
IT stack rationalization has become one of the least glamorous and most important jobs on a CTO’s desk. It is not flashy. It does not come with a launch event. But if your environment is bloated with overlapping platforms, half-adopted tools, redundant vendors, and unclear ownership, no amount of “innovation” is going to fix the drag that follows. Rationalization gives enterprises a clear inventory of what they have and a decision framework for what to keep, consolidate, replace, or retire before they migrate, modernize, or simplify.
That is the part the market still gets wrong. Too many organizations treat growth in tooling like proof of maturity. It is usually the opposite. More often, sprawl is a sign that the operating model is weak, architecture standards are inconsistent, and buying decisions are happening faster than governance. ISACA makes the same point from a security lens, more tools can create more moving parts, more credentials, and more opportunities for failure if they are not governed well.
At ATC, the practical view is this, IT stack rationalization is not an exercise in buying less. It is an exercise in buying with intent. The goal is not austerity. The goal is a stack that is easier to secure, easier to integrate, easier to support, and more tightly aligned to business outcomes. At ATC, we approach technology planning around business goals, guardrails, and measurable outcomes rather than disconnected platform decisions.
Most CTOs Do Not Have a Tool Problem, They Have a Decision Problem
When leaders say they have too many tools, that is usually true, but it is still not the root cause. The root cause is usually fragmented decision-making.
One business unit buys for speed. Another buys for local optimization. Security buys for coverage. Infrastructure buys for standardization. Finance gets pulled in after the contracts are signed. The result is a pile of point solutions that all made sense in isolation and make much less sense as a portfolio.
That is why IT stack rationalization needs to start with operating discipline, not a procurement freeze. If your organization has no shared principles for where tools fit, how they integrate, who owns them, and what success looks like, you will recreate the same sprawl six months after the cleanup.
What Is IT Stack Rationalization, Really?
For a technical leader, IT stack rationalization is the structured process of deciding what to keep, consolidate, replace, retire, or modernize across the portfolio. The language varies by framework, but the logic is remarkably consistent. The U.S. federal Application Rationalization Playbook provides a framework for evaluating and optimizing an application portfolio based on business value, technical fit, cost, and modernization needs. AWS guidance starts with a complete inventory and directional business case, then uses rationalization to identify migration candidates and wave plans. Microsoft’s 6 Rs model similarly gives teams a repeatable way to decide whether an application should be retained, retired, rehosted, replatformed, refactored, or repurchased.
That is why application portfolio rationalization should not be treated like a one-time cleanup project. It is a management discipline. Good CTOs revisit the portfolio as architecture, vendor landscapes, and business priorities change.
How Do You Know It Is Time for IT Stack Rationalization?
Usually, the signs show up before anyone says the phrase out loud.
If multiple tools claim to solve the same category of problem, if your teams export data between systems instead of integrating them, if security has blind spots because ownership is ambiguous, if support teams cannot tell which platform is authoritative, or if renewals keep happening because nobody wants to untangle dependencies, you are already paying the tax of sprawl.
That tax is not only financial. It is architectural and operational. Every duplicate tool adds another policy model, another integration path, another set of credentials, another admin surface, and another opportunity for drift. ISACA’s warning is worth taking seriously here, each additional tool introduces complexity and expands the attack surface if it is not tightly managed.
Why Tool Consolidation Fails When It Is Treated Like a Budget Exercise
This is where many programs go sideways. Leadership decides the estate is too expensive, so teams get told to cut vendors. That approach sounds rational and often fails for exactly the same reason the stack became messy in the first place, nobody defined the decision model.
Tool consolidation works when it is tied to architecture standards, workflow ownership, security controls, and measurable operational outcomes. It fails when the only question is cost. A cheaper stack that creates more manual work, more brittle integrations, or less visibility is not actually simpler. It is just underfunded complexity.
The better question is not “What can we remove?” It is “What should be the system of record, what should be the operational primary, and what should be retired because it no longer earns its place?”
How Should a CTO Prioritize IT Stack Rationalization?
The strongest approach is brutally practical.
Start with inventory. AWS and the federal playbook both emphasize that you cannot rationalize what you have not actually documented. That means applications, contracts, owners, integrations, support burden, business criticality, data sensitivity, and real usage, not assumed usage.
Then score the estate against four dimensions:
Business value
Does the tool materially improve revenue, service quality, productivity, or risk posture?
Technical fit
Does it align with your target architecture, identity model, integration standards, and observability approach?
Operational burden
How much human effort does it require to administer, support, patch, govern, and explain?
Portfolio overlap
Does another platform already provide the same capability more effectively?
This is where application portfolio rationalization becomes useful instead of theoretical. Once you score the portfolio, patterns emerge quickly. You find duplicate collaboration tools, underused analytics layers, security products that overlap in detection but not in workflow, and niche platforms still hanging around because the original buyer has moved on.
How to Rationalize Without Slowing the Business Down
This is the part smart CTOs care about most. They are not trying to “clean house” for the sake of aesthetics. They are trying to simplify the stack without creating political drag or operational disruption.
A practical sequence looks like this:
First, define your target architecture principles. The strongest roadmaps are tied to business goals and a clear model for how the environment should evolve.
Second, pick a few high-friction categories where the overlap is obvious. Identity-adjacent tools, project management platforms, endpoint visibility, workflow automation, and analytics are common places to start.
Third, designate primaries. In any critical capability area, one platform should have operational primacy. Supporting tools may still exist, but not with ambiguous authority.
Fourth, retire in waves. Do not force a dramatic big-bang consolidation unless the risk is contained and the migration path is proven. Rationalization should improve execution, not interrupt it.
That is what real IT stack rationalization looks like in practice. Less ideology, more sequencing.
The CTO Playbook, Buy Less Randomly, Govern More Intentionally
The organizations that do this well are not anti-tool. They are anti-chaos.
They do not let every purchase masquerade as innovation. They expect a business case, an integration path, an owner, and a retirement plan. They treat tool consolidation as an architecture decision, not just a finance decision. They use application portfolio rationalization to make future modernization easier, not harder. And they understand that IT stack rationalization is really about making the environment more governable.
That is the real next-gen posture. Not the biggest stack. Not the loudest vendor story. A cleaner, more intentional estate that gives the business speed without inheriting complexity it cannot manage.
In other words, IT stack rationalization is not about saying no to technology. It is about saying no to drift.
The post IT Stack Rationalization, A CTO’s Guide to Cutting Sprawl and Buying With Intent appeared first on Advanced Technology Consulting (ATC).
]]>The post The Next 3 Years of Enterprise IT, What CTOs Should Prepare for Now appeared first on Advanced Technology Consulting (ATC).
]]>
Most predictions about the future of enterprise IT are overly confident.
They assume linear progress. They assume adoption will keep pace with innovation. They assume organizations will move faster simply because the technology allows it.
That is not how this usually plays out.
The next three years are not going to be defined by what is possible. They are going to be defined by what organizations can actually operationalize under real constraints, technical, regulatory, financial, and organizational.
That is where the future of enterprise IT becomes more grounded and, in some ways, more difficult.
AI will expand, but so will the friction around it
There is no question that AI will continue to spread across the enterprise.
More use cases will move into production. More workflows will incorporate some form of automation or decision support. More vendors will embed AI into their platforms.
At the same time, the friction around AI will increase.
Questions around AI safety, model behavior, and accountability are already slowing down some deployments. As usage grows, those concerns become harder to ignore. Leaders will need clearer answers around how models behave, how outputs are validated, and where responsibility sits when things go wrong.
This is where the future of enterprise IT becomes less about capability and more about control.
Organizations that move forward without addressing these concerns will likely face setbacks. Organizations that overcorrect may struggle to move at all.
The balance between speed and safety becomes a defining challenge.
Privacy and compliance are becoming design constraints
Privacy used to be something you addressed after the system was built.
That approach no longer works.
As data becomes more distributed and more valuable, privacy and compliance requirements are starting to shape architecture decisions earlier in the process. Regulations continue to evolve, but even without new mandates, customer expectations are changing.
This creates a different design environment.
Systems need to account for:
- where data is stored
- how it is accessed
- how it is processed
- how it is shared across services and vendors
These are not edge considerations. They are core to how systems are built.
The future of enterprise IT will involve more trade-offs in this area. More flexibility often means more exposure. More control often means more complexity. There is no universal answer, only context-specific decisions.
Edge computing will matter more than expected
For a long time, edge computing has been positioned as a niche.
That is starting to shift.
As more workloads require real-time processing, local decision-making, or operate in environments with limited connectivity, the importance of edge computing increases. This is especially true in industries with distributed operations, physical environments, or latency-sensitive use cases.
What makes this interesting is not just the technology, but the architectural implications.
Edge introduces new considerations around:
- data synchronization
- security at distributed endpoints
- consistency across environments
- operational visibility
It also complicates governance and compliance, because data is no longer centralized.
This is one of the areas where the future of enterprise IT becomes more fragmented. Not everything will move to the cloud. Some things will move closer to where the work actually happens.
The cost conversation is not going away
Cost pressure is becoming a constant.
Cloud spend, vendor pricing, and operational overhead are all under more scrutiny. This is not a temporary adjustment. It is becoming a permanent part of how decisions are made.
What is changing is how early cost enters the conversation.
It is no longer just a post-deployment concern. It is part of design. Teams are being asked to think about cost alongside performance, scalability, and reliability.
This shift affects architecture decisions directly.
The future of enterprise IT will require more visibility into how design choices translate into spend. It will also require better alignment between engineering and financial expectations.
This is where many organizations are still catching up.
Complexity will continue to increase, not decrease
Despite efforts to simplify, most environments are becoming more complex.
More systems. More integrations. More vendors. More data flows. More dependencies.
New technologies do not replace old ones as quickly as expected. They layer on top. Legacy systems remain in place longer. Transitional architectures become semi-permanent.
This is one of the less optimistic realities of the future of enterprise IT.
Complexity is not going away. It is becoming something that needs to be managed more deliberately.
Organizations that assume simplification will happen naturally tend to struggle. Those that actively design for clarity, ownership, and control tend to perform better over time.
Talent and operating models will become a bigger constraint
Technology is only part of the equation.
Operating models are starting to matter more.
As environments become more complex and distributed, the way teams are structured, how decisions are made, and how responsibilities are defined becomes more important. Skill gaps are not just about tools, they are about how teams work together.
This is where some organizations will slow down, not because they lack access to technology, but because their operating model cannot support it.
The future of enterprise IT will be shaped as much by people and process as by platforms.
The real shift is toward intentionality
Across all of these trends, there is a common theme.
Less assumption. More intention.
Fewer decisions based on default narratives like “cloud-first” or “AI everywhere.” More decisions based on context, trade-offs, and actual business needs.
This is where the conversation is already starting to shift.
The strongest teams are not chasing every trend. They are making deliberate choices about where to invest, where to hold back, and where to wait.
That discipline is becoming a differentiator.
What CTOs should actually prepare for
Preparation does not mean predicting the future perfectly.
It means building an environment that can adapt.
That includes:
- architectures that can evolve without constant rework
- governance models that support speed and control
- clearer visibility into data, cost, and performance
- operating models that align teams with outcomes
It also means being realistic about constraints.
The future of enterprise IT is not going to be defined by the organizations that adopt the most technology. It will be defined by the ones that can operationalize it effectively.
The better question for CTOs
Instead of asking what trends to follow, a better question is:
Where will our current approach break as these trends become real?
That question shifts the focus.
It highlights the gaps that matter. It forces earlier decisions. It makes the future less abstract and more actionable.
Because the future of enterprise IT is not something that arrives all at once.
It shows up gradually, through the pressure it puts on the systems you already have.
The post The Next 3 Years of Enterprise IT, What CTOs Should Prepare for Now appeared first on Advanced Technology Consulting (ATC).
]]>The post What 100+ Client Conversations Taught Us About What’s Actually Working in IT appeared first on Advanced Technology Consulting (ATC).
]]>
There is no shortage of opinions in enterprise IT.
Every vendor has a point of view. Every framework has a model. Every conference has a new set of priorities. On paper, it can feel like the path forward is well defined.
In practice, it is not.
What actually works tends to look very different from what gets the most attention. That becomes clear after enough conversations with technical leaders who are dealing with real constraints, not idealized environments.
Across those conversations, patterns start to emerge. Not best practices in the traditional sense, but signals. What is gaining traction. What is quietly being deprioritized. What is creating real impact versus what is mostly noise.
That is where enterprise IT best practices need to be grounded, not in theory, but in what holds up under pressure.
The teams that move fastest are not the ones with the most tools
There is still a tendency to equate capability with tooling.
More platforms. More dashboards. More integrations. The assumption is that a broader stack creates more flexibility.
In reality, the opposite often happens.
Environments become harder to manage. Data becomes fragmented. Ownership becomes unclear. Integration becomes a constant source of friction. The system slows down under its own complexity.
The teams that are moving faster tend to look different.
They have fewer tools. They are more opinionated about what stays and what goes. They prioritize consistency over optionality in areas that do not need variation.
This is one of the quieter shifts in enterprise IT best practices. Simplification is becoming a competitive advantage.
Platform teams are working, but only when they are treated like products
Platform teams show up in almost every conversation.
Most organizations understand the idea. Centralize common capabilities, create reusable services, reduce duplication, improve consistency. On paper, it makes sense.
In practice, results are mixed.
Where platform teams struggle, the issue is usually not the concept. It is how the platform is treated. If it is managed like an internal project, it tends to become rigid, underutilized, or disconnected from what teams actually need.
Where it works, the mindset is different.
The platform is treated like a product. It has users. It has a roadmap. It evolves based on feedback. It is measured by adoption, not just delivery.
That distinction is subtle, but it is one of the clearer patterns showing up in enterprise IT best practices right now.
SRE is less about reliability and more about alignment
Site reliability engineering still carries a strong association with uptime and performance.
Those are important, but they are not the full story.
In the environments where SRE is working well, it is acting as a bridge between development and operations. It is creating shared ownership of reliability, not just monitoring it after the fact.
This changes how systems are built.
Reliability becomes part of design, not just response. Trade-offs are made earlier. Failure modes are considered upfront. Teams have clearer expectations about what “good” looks like in production.
Where SRE struggles, it is often because it is layered on top of existing silos instead of changing how those silos interact.
That is why its impact varies so much across organizations.
FinOps is gaining traction, but expectations are still off
FinOps is one of the fastest-growing areas of focus, especially as cloud costs continue to rise.
Most organizations recognize the need for better visibility and control. The challenge is in how FinOps is applied.
In some environments, it becomes a reporting function. Teams track spend, generate insights, and highlight inefficiencies. That has value, but it rarely changes behavior on its own.
Where FinOps is working, it is embedded into decision-making.
Engineering teams understand cost as part of their design choices. Trade-offs between performance and spend are visible earlier. Cost is treated as a dimension of architecture, not just an outcome.
This is still evolving, but it is one of the clearer signals in enterprise IT best practices. Cost awareness is shifting left.
What is getting overhyped right now
There are also patterns around what is not working as well as expected.
Some of the most common:
The idea that more automation always leads to better outcomes. In reality, poorly designed automation often amplifies existing problems.
The assumption that adopting a new framework will solve structural issues. Frameworks can help, but they do not replace discipline.
The belief that AI will quickly eliminate operational complexity. In practice, it often exposes it.
None of these ideas are wrong. They are just oversimplified.
This is where many organizations get stuck. They adopt the language of modern IT without fully addressing the underlying challenges.
What is actually working, even if it gets less attention
The more effective patterns are less flashy.
Clear ownership of systems and outcomes. Fewer, better-defined priorities. Stronger alignment between architecture and business goals. Willingness to say no to additional tools or initiatives that do not clearly add value.
These are not new ideas.
What is changing is how consistently they are being applied. In environments where they are taken seriously, they compound. Systems become easier to operate. Teams become more focused. Progress becomes more predictable.
This is the part of enterprise IT best practices that does not always get highlighted, because it is not tied to a specific technology or trend.
The gap between conversation and execution
One of the more interesting patterns is how often organizations know what they should do.
The gap is not awareness. It is execution.
Leaders understand the need for simplification. They recognize the value of platform thinking. They see the importance of cost discipline. They are aware of the risks of overengineering.
The challenge is making those ideas stick inside complex environments with competing priorities.
That is where most of the real work is happening.
The better question for CTOs
Instead of asking what the latest best practice is, a better question is:
Which of these practices are we actually applying consistently, and where are we still operating by exception?
That question is less comfortable, but more useful.
It shifts the focus from adopting new ideas to reinforcing the ones that already matter. It also highlights where the organization is creating unnecessary complexity or misalignment.
Enterprise IT best practices are not hard to find.
They are hard to execute consistently.
That is where the difference shows up.
The post What 100+ Client Conversations Taught Us About What’s Actually Working in IT appeared first on Advanced Technology Consulting (ATC).
]]>