The post Keeping timezone data current appeared first on andreas.heigl.org.
]]>British Columbia did so in March already whereas Alberta decided so in June, the Northwest Territories in August and Manitoba in September.
As is the usual process shortly after the decission was made, there was a new version of the timezone-database released so that the information is available only with a short delay to everyone that needs it.
Who needs that? Well… That database is on every computer whether Linux, Windows or MacOS, on every mobile device from Android to iOS and on every Smartwatch out there. In every GPS in your car, yacht or plane. More or less in any electronic device that keeps track of time. So yes! Your smart-fridge might also be running it.
I was now recently challenged to do some updates of data that was converted wrongly based on the information in the old versions of the database and to convert it to the new version of the database (I have written why it is a bad idea to do that previously)
Only to end up in its own kind of hell.
It all started with something that I realized quite some time back: The International Components for Internationalization – in Short ICU – ship with their own version of the timezone database. And the ICU version in some linux-distributions is notorioulsy outdated. And due to the ICU version being outdated, the timezone-data is also outdated. Not by a month or one or two versions. We are talking years. The probably still widely used Ubuntu LTS version 24.04 – codename Noble Numbat – ships with ICU version 74.2 – released in December 2023. And that ships with the timezone database 2023c from March 2023.
When I realized that, I started digging into how to update the ICU version so that PHP applications can actually get the latest ICU as well as the latest timezone-data.
And then I had to dig into that deeper. And I figured out that it is much easier to do the updates for the ICU timezone-data (not the update of the ICU package itself though! Just the timezone-data!) by installing a package called tzdata-icu!
Install that on your ubuntu machine and you are up-to-date! (Sidenote: Why that package is not automatically installed when installing the ICU package is totally beyond me! Why would one want to use the ICU package that is aweseome for date-formatting but use the outdated timezone information for that?)
Or so I thought…
It turned out that the release of the timezone-database does not mean that there will be a corresponding release of the tzdata-package (or the tzdata-icu package) in Ubuntu. That can take a while. And when it is available it is first available in the proposed channel and then some days later moves to the update channel…
It looked like the tzdata package of Ubuntu for the tzdb release 2026b was released in the update channel in July. Remember: The release of the tzdb was in March.
So. Looks like everything is solved.
Finally I had everything up-to-date. Slightly delayed due to the package-delay, but still!
Along came GithubActions.
Where I installed php running on an Ubuntu system.
And suddenly all my tests that require the latest timezone data failed. Looks like the Ubuntu runner used outdated data
So then… Luckily Derick Rethans maintains the timezonedb package on pecl and that is usually available for PHP with a very short delay! So I installed setup-php with extension: timezonedb and everything was good. (I actually had to use timezonedb-2026.5 but that was due to a bug that should be fixed with the next release!)
What did I learn from this:
- Just because ther eis a new release of the IANA timezone database doesn’T mean that there is immediately a new release for my distribution
- The ICU extension uses its own timezone database. And by default a really old one
- The timezonedb extension for PHP is usually really up-to-date and a safe way to update the timezones for PHP.
- Updating the timezones for ICU can be really easy depending on the distro
- The challenge is not creating code that works correctly with timezones. It’s getting the correct data on time.
The post Keeping timezone data current appeared first on andreas.heigl.org.
]]>The post Bringing “The PHP Community” together appeared first on andreas.heigl.org.
]]>What is PHPVerse?
PHPVerse is an online conference organized by Jetbrains and free to attend for everyone registered.
The idea is to connect different parts of the splitted PHP-Community which I endorse! So for this edition there were people from the Symfony-, WordPress-, Laravel- and the Drupal-Community doing sessions along with people vocal on the internals mailinglist, maintaining the PHP package manager and from the PHP Foundation.
But this is not about the content that these people brought. What hit me were three fundamental things about “The Community” that in my opinion need to be addressed differently and why I am increasingly weary of such events.
1. The Community
What community are we talking about here. Or let me ask this question slightly different: Which parts of “The Community” are we **not** reaching?
I realised that when I wanted to toot about the event: It doesn’t have an account on mastodon…

Yes! I know! There are several other social networks out there.
And on the main website of the event there are several social networks showing up right at the top: X, Facebook, LinkedIn and BlueSky.
Given that there is such a thing as a PHP-Community Mastodon server (at https://phpc.social) where an integral part of the PHP-Community is “hanging out” it seems like an odd choice to not at least include that in that list.
I understand that a “Free” event still needs to pay off for someone and that it is far easier to track “interactions” on walled-garden “social” networks. But if you want to do something **for** the community without a vital part **off** the community, that seems like “Doing it wrong ”
2. The time
Interesting was also the timing. When doing an online event, it is really hard to please everyone. Especially when you want to do an event in “only” 8 hours. Due to the nature of the world the PHP-Community is online almost 24h a day. It is spanning from New-Zealand, Australia and Japan on the east side all the way over to the Americas with Alaska and Hawaii reaching out furthest west. (Yes! There are some people even nearer to the date-line, I know!).
The event was set to happen from 11:00 UTC to 16:30 UTC. Which means 23:00 through 4:30 in Auckland. That requires some commitment to follow this event from there. Even as far west as the Indian Subcontinent – where the event took place from 16:30 through 22:00 that requires some commitment to follow that late into the evening.
When I realized that I immediately had to think about this tweet from 2021:
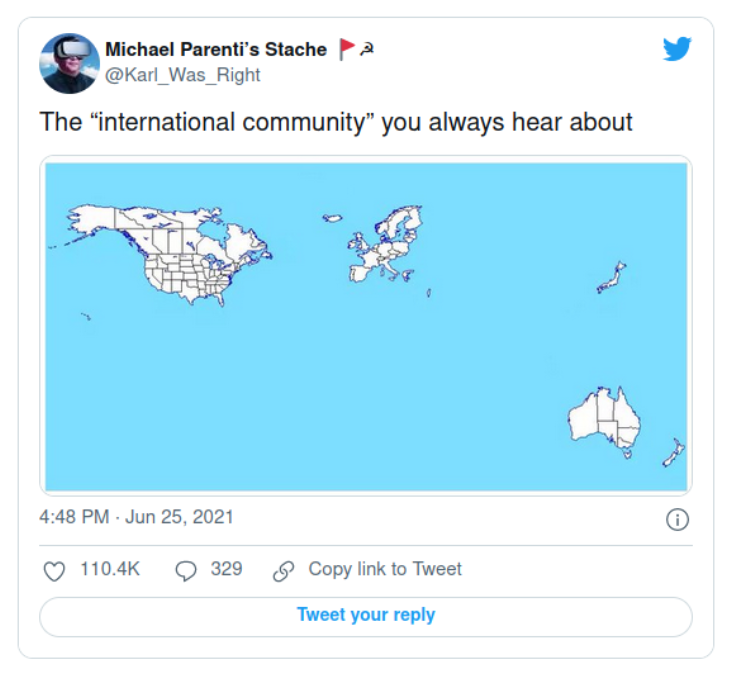
Only that this time event Japan, Australia and New Zealand are missing.
Again: “The Community” is actually only a part of the community that we are talking about.
3. The people
And then I stumbled upon a toot from Pauline Vos:
Just saw the trailer for the PHP documentary shown at PHPVerse…
ZERO women? Are you serious? 5 women (including at least 3 past or present core developers that I know of, and the executive director) on the @thephpf , and the story of PHP includes ZERO women?
Not to mention those prominent in the community that aren’t part of the Foundation itself. You can’t be serious.
Yes! There are not that many women around in the PHP Community. One might think. But actually there are. But with this kind of marketing, that amount will – to put it mildly – not increase.
Again: A huge part of the community not only lost but actually alienated.
Takeaway
To summarize: Time, Interaction and trailer-Content indicate that “The Community” the PHPVerse is talking about, is the European and North-American male dominated part that is still hanging out on the BigCorporation networks.
That is not the PHP Community I know and that I consider myself a part of. On the contrary! That seems to be the image that the PHP Community needs to get away of to actually become a world-wide, welcoming, vibrant, and healthy community.
Oh! And before you start responding with reasons why something doesn’t work or can’t be done differently: Think about this:
Where there’s a will, there’s a way; where there isn’t, there’s an excuse.
The post Bringing “The PHP Community” together appeared first on andreas.heigl.org.
]]>The post Code-Coverage with PCOV in a mono-repo appeared first on andreas.heigl.org.
]]>To give you a bit of background, imagine a project that uses 2 separate folders where one contains the business-logic and one contains the framework-related code. The framework-related part contains a lot of integration and end-to-end test that – of course – also use and therefore test the business-logic.
Every PullRequest runs the tests both from the bunsiness-logic part as well as from the framework-related part. And to give the developers feedback how well the changed code is covered with tests we collect coverage data and generate a patch-coverage report. I wrote about that some time back. So we now get a comment each in the PR that contains the untested lines in the business-logic related part and the framework-related part respectively.
That worked flawlessly for the business-logic related part as those were mostly unit-tests that do not rely upon the framework-related code.
The framework-related part though didn’t work that great. It always showed the business-logic related parts as untested even though I knew they were tested.
So… Why?
After some digging I realized that there is a difference in how the coverage is created between Xdebug and pcov – yes! There is obviously a difference as those are different tools. But there is also a difference in what is included in the reports.
And today I figured out what it was and why it broke our proces in our specific setup in GitHub actions.
For a start: We have our code in two folders: business and framework.
We also have a framework/phpunit.xml file that contains this code:
<?xml version="1.0" encoding="UTF-8"?>
<phpunit
    xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
    xsi:noNamespaceSchemaLocation="https://schema.phpunit.de/12.1/phpunit.xsd"
    processIsolation="false"
    stopOnFailure="false"
>
  <coverage/>
  <source>
    <include>
      <directory>src</directory>
      <directory>../business/src</directory>
    </include>
  </source>
</phpunit>
So coverage shall be collected from the current src folder as well as from the business/src folder.
This works as expected when you run phpunit with Xdebug as coverage-generator.
With pcov as coverage-generator it worked locally as expected.
But not in our GitHub Actions…
Enter pcov.directory
After a bit of digging I learned that there is the pcov.directory ini-setting that determines which code is considered for coverage. So I tested my GitHub Actions by adding some test-code like this:
jobs:
  tests:
    steps:
      - name: "Checkout"
        uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v6
        with:
          ref: ${{ github.event.pull_request.head.ref }}

      - name: "Install PHP"
        uses: shivammathur/setup-php@44454db4f0199b8b9685a5d763dc37cbf79108e1 # v2
        with:
          extensions: "intl, pdo_mysql, zip, imap, xml, soap, apcu, redis"
          php-version: "8.4"
          coverage: "pcov"
      - name: "check pcov.directory"
        run: |
          php -i | grep pcov
Running this in GitHub Actions provided me with output similar to this:
Run php -i | grep pcov
/etc/php/8.4/cli/conf.d/20-pcov.ini,
pcov
pcov.directory => /home/runner/work/<org-name>/<repo-name>
pcov.exclude => none
pcov.initial.memory => 65336 bytes
pcov.initial.files => 64
/home/runner/work/<org-name>/<repo-name> was exactly what i expected! So why the heck does it seemingly not work?
After some more testing I realized that I was at one point doing a cd framework before running PHPUnit.
- name: "Run tests"
  run: |
    cd framework
    vendor/phpunit/phpunit/phpunit --coverage-php /tmp/${{ github.sha }}_coverage.cov
Should that cause some issues?
So I added the php -i | grep pcov after the PHPUnit run like this:
- name: "Run tests"
  run: |
    cd framework
    vendor/phpunit/phpunit/phpunit --coverage-php /tmp/${{ github.sha }}_coverage.cov
    php -i | grep pcov
And what was that? Suddenly I got
pcov.directory => /home/runner/work/<org-name>/<repo-name>/framework/src
Suddenly the pcov directory was set to something totally different. And with that setting it was clear that I couldn’t get what I expected as now only content from framework/src/ would be considered as covered. And everything from the business folder was not considered for coverage.
So the only question left was whether that was something happening deep in PHPUnits logic or just based on changing the directory.
Long story short: It’s just based on the change directory. In essence setup-php sets up pcov so that the current folder is considered as pcov.directory. As pcov itself adds src when that folder is available that explains the changed folder.
But is there a way to change that? To use a fixed folder despite the current working directory being changed?
Yes! There is.
I added ini-values: "pcov.directory=$GITHUB_WORKSPACE" to the setup-php directive like this:
      - name: "Install PHP"
        uses: shivammathur/setup-php@44454db4f0199b8b9685a5d763dc37cbf79108e1 # v2
        with:
          extensions: "intl, pdo_mysql, zip, imap, xml, soap, apcu, redis"
          ini-values: "pcov.directory=$GITHUB_WORKSPACE"
          php-version: "8.4"
          coverage: "pcov"
And all of a sudden the pcov.directory stayed regardless of where I changed the working directory to.
And so with this little change I was again able to get the coverage-data from the business folder whenever i run tests in the framework folder.
Helpful links:
- https://github.com/shivammathur/setup-php#pcov
- https://github.com/krakjoe/pcov/issues/86
- https://github.com/krakjoe/pcov?tab=readme-ov-file#configuration
The post Code-Coverage with PCOV in a mono-repo appeared first on andreas.heigl.org.
]]>The post Property-Hooks for the win appeared first on andreas.heigl.org.
]]>But just today I had one of those situations where they helped me combine legacy code with new functionality.
The starting position
I am working on a project where we are using PDO and especially PDO::FETCH_CLASS to create Objects from our database-content.
So the code looks something like this:
function getAllFoos() : array
{
    $stmt = $this->executePdoQuery(<<<SQL
        SELECT * FROM table
        SQL);
    $stmt->setFetchMode(PDO::FETCH_CLASS, Foo::class);

    return $stmt->fetchAll();
}
Foo looks something like this:
final class Foo
{
    public string a;
    public string b;
}
And the database-table looks something like this:
CREATE TABLE foo (
    a VARCHAR(20),
    b VARCHAR(20),
)
Everything worked as expected and calling getAllFoos got me a list of Foo-objects.
So Far so good.
Now I wanted to add a new field to the Foo-object and that should contain an Enum. Easy peasy.
final class Foo
{
    public string a;
    public string b;
    private Status $status;
}

enum Status: string {
    case Open = 'open';
    case Closed = 'closed';
}
Now I need to update the database
ALTER TABLE foo ADD COLUMN `status` VARCHAR(10) NOT NULL DEFAULT 'open';That’s it!
When testing that though I found that it wasn’t because now everything blew up when calling getAllFoos ….
What happened?
Well, as expected the fetchAll tried to hydrate the values of the Foo object wth the values from the DB. But the DB contains a string whereas the Foo object expects the respective enum.
There is no out of the box solution to this. PDO has no idea how to convert this database-value into something the object understands (it could infer the expected enum-type from the type-hint but that can get out of hand rather quickly when it’s not an enum bot any other object that doesn’t have a ::from method or…)
Property Hooks to the rescue.
So I had to find my own way around this. And here property hooks are awesome when one has to adapt to legacy code.
So this is what my Foo class now looks like
final class Foo
{
    public string a;
    public string b;
    private Status $status {
        set(string|Status $value) {
            if (is_string($value)) {
                $value = Status::from($value);
            }

            $this->status = $value;
        }
    }
}
Works like a charm now!
The post Property-Hooks for the win appeared first on andreas.heigl.org.
]]>The post Content-Negotiation appeared first on andreas.heigl.org.
]]>What does that have to do with Content-Negotiation? Well: We did negotiate that we would communicate in english. Comming back to me with some language that we already had established I can’t understand doesn’t make sense. And I might just not understand what they want.
HTTP has a similar process, described and defined in RFC 7231. There are in general 2 possible options: A proactive and a reactive approach. The main thing in both is that the client can provide a preference and that then
applies to any content in the response, including representations of the target resource, representations of error or processing status, and potentially even the miscellaneous text strings that might appear within the protocol.
So regardless of what happens in between, when the client sends a content-negotiation header like Accept: text/html then the server responds with data in HTML format. Whether that is the requested resource or an error-message explaining what went wrong or something else.
This is in my opinion important to understand! When the client sends an Accept header all responses have to be in the requested format!
The server can not send JSON back just because it ran into an error. That’s like my waiter talking to me in french again because they ran into a problem with the order. I don’t understand what they want. I might not even realize that they ran into an error.
Content Negotiation usually uses one or multiple of Accept, Accept-Encoding, Accept-Charset and/or Accept-Language.
And the Server then responds with Content-Type, Language, Charset.
To make things easier for the server one can define ranges, like “I accept German, but I am also able to understand swiss-german and in the worst case English”. That would look like this
Accept-Language: de-DE,de-CH;q0.8,en;q0.5The same is possible with mime-types:
Accept: text/html;text/xml;0.9,application/json;0.7,text/*;0.5,*/*;0.2I prefer HTML, if that’s not possible, send me XML, if that’s also not possible, send me JSON. If that is also not possible please anything that is text before sending me whatever you got.
In that case the server has a choice to send something they understand.
But when the client sends Accept: application/json then the only thing the server can return is… JSON. The client doesn’t understand anything else.
And according to the link from the beginning even an error would need to be in JSON format. Because that is what the client understands. Nothing else.
Does that raise a concern?
Hard Coded Responses
Exactly! In a lot of applications we return hard-coded some hard-coded formatted response.
We break the Content-Negotiation for mime-types.
One of the – in my eyes – biggest drawbacks of PSR-7 is actually that we are returning a response. And that response is already formatted ready to be sent to the client.
Instead of leaving the actual formatting to a – for me as a programmer – transparent process that uses the result of the content negotiation to format some DTO in the preferred way. Either by passing it to some kind of templating engine or some serializer for some format.
Most frameworks already allow that in the error case where an Exception is converted into the (hopefully) correct format. But on the actual content we are not doing that.
I actually at one point created a library for a project of mine that wraps a DTO into a Response and then relies upon a Middleware to format that DTO into the actual response-content.
But that is a workaround to fix the shortcoming in PSR-7 as well as in Symfonys Response implementation.
I have no good idea on how to solve that apart from such a quirk.
If you have a good idea, feel free to tell me!
The main thing though is: Make sure your server always returns the expected content in terms of type and language. And we should not have to talk about encoding (UTF-8) and charset (Unicode) any more! Though… There are some very esoteric clients out there….
And when you can’t resolve to a common ground: Send a 406 response!
The post Content-Negotiation appeared first on andreas.heigl.org.
]]>